# Web Search Configuration (https://www.librechat.ai/docs/configuration/librechat_yaml/object_structure/web_search)
The `webSearch` configuration allows you to customize the web search functionality within LibreChat, including search providers, content scrapers, and result rerankers.
## Overview
The web search feature consists of three main components:
1. **Search Providers**: Services that perform the initial web search
2. **Scrapers**: Services that extract content from web pages
3. **Rerankers**: Services that reorder search results for better relevance
## Example
```yaml filename="webSearch"
webSearch:
# Search Provider Configuration
serperApiKey: "${SERPER_API_KEY}"
searxngInstanceUrl: "${SEARXNG_INSTANCE_URL}"
searxngApiKey: "${SEARXNG_API_KEY}"
searchProvider: "serper" # Options: "serper", "searxng", "tavily", "keenable"
# Optional: query options sent to a SearXNG instance
searxngSearchOptions:
engines: "google,bing,startpage" # Default: "google,bing,duckduckgo"
language: "en" # Default: "all"
# Tavily Configuration (search and/or scraper)
tavilyApiKey: "${TAVILY_API_KEY}"
# Optional: custom Tavily-compatible endpoints
tavilySearchUrl: "${TAVILY_SEARCH_URL}"
tavilyExtractUrl: "${TAVILY_EXTRACT_URL}"
# Keenable Configuration (search and/or scraper; all credentials optional)
keenableApiKey: "${KEENABLE_API_KEY}"
keenableApiUrl: "${KEENABLE_API_URL}"
keenableSearchOptions:
maxResults: 8
site: "example.com"
attributionTitle: "LibreChat"
timeout: 15000
keenableScraperOptions:
attributionTitle: "LibreChat"
timeout: 15000
# Scraper Configuration
firecrawlApiKey: "${FIRECRAWL_API_KEY}"
firecrawlApiUrl: "${FIRECRAWL_API_URL}"
firecrawlVersion: "${FIRECRAWL_VERSION}"
scraperProvider: "firecrawl" # Options: "firecrawl", "serper", "tavily", "keenable"
# Reranker Configuration
jinaApiKey: "${JINA_API_KEY}"
jinaApiUrl: "${JINA_API_URL}"
cohereApiKey: "${COHERE_API_KEY}"
rerankerType: "jina" # Options: "jina", "cohere", "none"
# General Settings
scraperTimeout: 7500 # Timeout in milliseconds for scraper requests (default: 7500)
safeSearch: 1 # Options: 0 (OFF), 1 (MODERATE - default), 2 (STRICT)
# Required for deliberately private self-hosted provider endpoints
allowedAddresses:
- "searxng:8080"
```
## SSRF Protection and Private Providers
LibreChat validates each connection it opens for web search, scraping, and reranking. Private, loopback, link-local, and cloud-metadata destinations are blocked by default, including redirect hops and hostnames that resolve to a private address at connect time.
Use `webSearch.allowedAddresses` when a configured SearXNG, Firecrawl, Jina, Tavily-compatible, Keenable-compatible, or related provider endpoint is deliberately private:
```yaml filename="webSearch / allowedAddresses"
webSearch:
searxngInstanceUrl: "${SEARXNG_INSTANCE_URL}"
allowedAddresses:
- "searxng:8080"
- "10.0.0.5:3002"
- "[fd00::5]:8080"
```
This field is an SSRF exemption list, not a strict allowlist. Public destinations remain available. Entries must be exact `host:port`, `private.ip:port`, or `[ipv6]:port` pairs; URLs, paths, CIDR ranges, bare hosts/IPs, and public IP literals are rejected. An exempted hostname trusts whichever private IP it resolves to on that port, so prefer a private IP literal and list only names whose DNS you control.
LibreChat automatically exempts a configured HTTP(S) forward-proxy endpoint so it can be reached. When the proxy carries a request, it resolves the destination and must enforce destination egress itself. `NO_PROXY` can make a request direct, where LibreChat's connection guard still applies. The guard covers connections LibreChat opens to provider APIs; it cannot constrain a page URL that a third-party scraper receives as request data and fetches on its own infrastructure.
## Search Providers
### searchProvider
### serperApiKey
**Note:** Get your API key from [Serper.dev](https://serper.dev/api-keys)
### searxngInstanceUrl
### searxngApiKey
**Note:** This is optional and only needed if your SearXNG instance requires authentication.
### searxngSearchOptions
**Subkeys:**
`searxngSearchOptions` reaches SearXNG through the search tool in `@librechat/agents`, and needs `@librechat/agents` v3.6.9 or later. Releases built against an earlier version ignore the block rather than failing to start, so an instance that keeps returning default results may simply be running an older build.
**Example:**
```yaml filename="webSearch"
webSearch:
searchProvider: "searxng"
searxngInstanceUrl: "${SEARXNG_INSTANCE_URL}"
searxngApiKey: "${SEARXNG_API_KEY}" # Optional
searxngSearchOptions:
engines:
- google
- bing
- startpage
- qwant
language: "en"
timeRange: "month"
timeout: 10000
```
`engines` also accepts the comma-separated form SearXNG itself uses, so this is equivalent to the list above:
```yaml filename="webSearch"
webSearch:
searxngSearchOptions:
engines: "google, bing, startpage, qwant"
```
#### Choosing engines
Engine names must match engines that are enabled on your own instance, and two things follow from that:
- SearXNG ignores an engine it does not recognize instead of reporting an error. A typo, or an engine that is disabled on your instance, shows up as fewer results rather than as a failure.
- The valid names are instance-specific. Check the enabled list at `https://your-instance/config`, which returns JSON including every enabled engine, or open the **Engines** tab of your instance preferences page.
The default is `google,bing,duckduckgo`. SearXNG aggregates whatever the selected engines return, so one blocked engine costs you its share of the results rather than the whole response, and a search only comes back empty when every selected engine fails or returns nothing.
DuckDuckGo is the engine in that default set most likely to be blocked, since it serves CAPTCHAs to most self-hosted instances. With only three engines in the set, losing it at the same time as a rate-limited Google or Bing is a common way to end up with no results at all. Setting `engines` explicitly, leaving DuckDuckGo out, and listing more than three engines all reduce that risk.
Engines that answer quickly and tolerate self-hosted traffic make the best starting set, for example:
```yaml filename="webSearch"
webSearch:
searchProvider: "searxng"
searxngInstanceUrl: "${SEARXNG_INSTANCE_URL}"
searxngSearchOptions:
engines:
- google
- bing
- brave
- startpage
- qwant
```
Adding more engines widens coverage but also slows every search down, since SearXNG waits on the slowest engine in the set before responding. Keep `timeout` in mind when you grow the list.
#### What these options do not control
- **Safe search** is not part of this block. It comes from the top-level [`safeSearch`](#safesearch) key and is forwarded to SearXNG as `safesearch`.
- **Result categories** are chosen per query by LibreChat, which maps the search type to `general`, `images`, `videos`, or `news`. They cannot be overridden here.
- **Page number and result format** are fixed. LibreChat always requests page 1 in JSON format, which is why your instance must have `json` enabled under `formats`.
### tavilyApiKey
**Note:** Get your API key from [Tavily](https://app.tavily.com/home)
### tavilySearchUrl
### tavilyExtractUrl
### tavilySearchOptions
**Subkeys:**
### keenableApiKey
### keenableApiUrl
The page-fetch endpoint is configured separately with the environment-only `KEENABLE_FETCH_URL` variable.
### keenableSearchOptions
## Scrapers
### firecrawlApiKey
**Note:** Get your API key from [Firecrawl.dev](https://docs.firecrawl.dev/introduction#api-key)
### firecrawlApiUrl
**Note:** This is optional and only needed if you're using a custom Firecrawl instance.
### firecrawlVersion
### scraperProvider
### firecrawlOptions
**Subkeys:**
#### formats
#### includeTags
#### excludeTags
#### headers
#### waitFor
#### timeout
#### maxAge
**Note:** If you do not need extremely fresh data, enabling this can speed up your scrapes by 500%.
#### mobile
#### skipTlsVerification
#### blockAds
#### removeBase64Images
#### parsePDF
#### storeInCache
#### zeroDataRetention
#### location
#### onlyMainContent
#### changeTrackingOptions
**Example:**
```yaml filename="webSearch"
webSearch:
firecrawlApiKey: "${FIRECRAWL_API_KEY}"
firecrawlOptions:
formats: ["markdown", "rawHtml"]
includeTags: ["main", "article", ".content"]
excludeTags: ["nav", "footer", ".ads"]
waitFor: 2000
timeout: 10000
mobile: false
blockAds: true
onlyMainContent: true
location:
country: "US"
languages: ["en"]
```
**Note:** For detailed information about Firecrawl scraper options and defaults, see the [Firecrawl API Documentation](https://docs.firecrawl.dev/api-reference/endpoint/scrape).
### tavilyScraperOptions
**Subkeys:**
**Example:**
```yaml filename="webSearch"
webSearch:
searchProvider: tavily
scraperProvider: tavily
tavilyApiKey: "${TAVILY_API_KEY}"
# Optional: custom Tavily-compatible endpoints
# tavilySearchUrl: "${TAVILY_SEARCH_URL}"
# tavilyExtractUrl: "${TAVILY_EXTRACT_URL}"
tavilySearchOptions:
searchDepth: basic
maxResults: 5
topic: general
tavilyScraperOptions:
extractDepth: basic
```
**Note:** For detailed information about Tavily API options, see the [Tavily API Documentation](https://docs.tavily.com).
### keenableScraperOptions
Keenable can provide search, page fetch, or both. Its public endpoints work without a key; the optional `keenableApiKey` raises rate limits. Set `rerankerType: "none"` to avoid requiring a reranker key:
```yaml filename="webSearch"
webSearch:
searchProvider: keenable
scraperProvider: keenable
rerankerType: none
# keenableApiKey: "${KEENABLE_API_KEY}" # Optional
# keenableApiUrl: "${KEENABLE_API_URL}" # Optional search endpoint
keenableSearchOptions:
maxResults: 8
# site: example.com
keenableScraperOptions:
timeout: 15000
```
## Rerankers
### jinaApiKey
**Note:** Get your API key from [Jina.ai](https://jina.ai/api-dashboard/)
### jinaApiUrl
**Note:** This is optional and only needed if you're using a custom Jina instance.
### cohereApiKey
**Note:** Get your API key from [Cohere Dashboard](https://dashboard.cohere.com/welcome/login)
### rerankerType
## General Settings
### scraperTimeout
### safeSearch
**Note:** Safe search levels align with standard search API conventions. MODERATE filtering is enabled by default to provide reasonable content filtering while maintaining search effectiveness. Tavily does not inherit this global setting by default; use `tavilySearchOptions.safeSearch` only if your Tavily account supports `safe_search`.
## Notes
- API keys can be configured in two ways:
1. Set the environment variables specified in the YAML configuration
2. If environment variables are not set, users will be prompted to provide the API keys via the UI
- The configuration supports multiple services for each component (providers, scrapers, rerankers)
- If a specific service type is not specified, the system will try all available services in that category
- Safe search provides three levels of content filtering: OFF (0), MODERATE (1), and STRICT (2)
- Tavily does not inherit the global safe search setting by default; set `tavilySearchOptions.safeSearch` explicitly only when your Tavily account supports `safe_search`
- Keenable supports keyless search and page fetch; its optional key raises public rate limits, and its fetch URL override is environment-only
- SearXNG query behavior (engines, language, time range, request timeout) is configured under `searxngSearchOptions`; see [Choosing engines](#choosing-engines) if searches come back empty
- Never put actual API keys in the YAML configuration - only use environment variable names
## Setting Up SearXNG
SearXNG is a privacy-focused meta search engine that you can self-host.
For more information, see the [official SearXNG documentation](https://docs.searxng.org/).
Here are the steps to set up your own SearXNG instance for use with LibreChat:
### Using Docker Desktop
1. **Search for the official SearXNG image**
- Open Docker Desktop
- Search for `searxng/searxng` in the **Images** tab
- Click **Run** on the official image to automatically pull down and run a container of the image
2. **Running the container**
- Expand the **Optional Settings** dropdown in the proceeding panel that appears once the download completes
- Set your desired configuration details (port number, container name, etc.)
- Click **Run** to start the container
3. **Configure SearXNG for LibreChat**
- Navigate to the `Files` tab in Docker Desktop
- Go to `/etc/searxng/settings.yaml`
- Open the file editor
- Navigate to the `formats` section
- Add `json` as an acceptable format so that LibreChat can communicate with your instance
- Save the file
4. **Restart the container**
- Restart the container for the changes to take effect
#### Video Guide:
Here's a video to guide you through the process from start to finish in about a minute:
**Note:** In this example, the instance URL is http://localhost:55011 (port number found under the container name in the top left at the end of the video)
### Configuring LibreChat to use SearXNG
You can configure SearXNG in LibreChat within the UI or through `librechat.yaml`.
#### UI Configuration
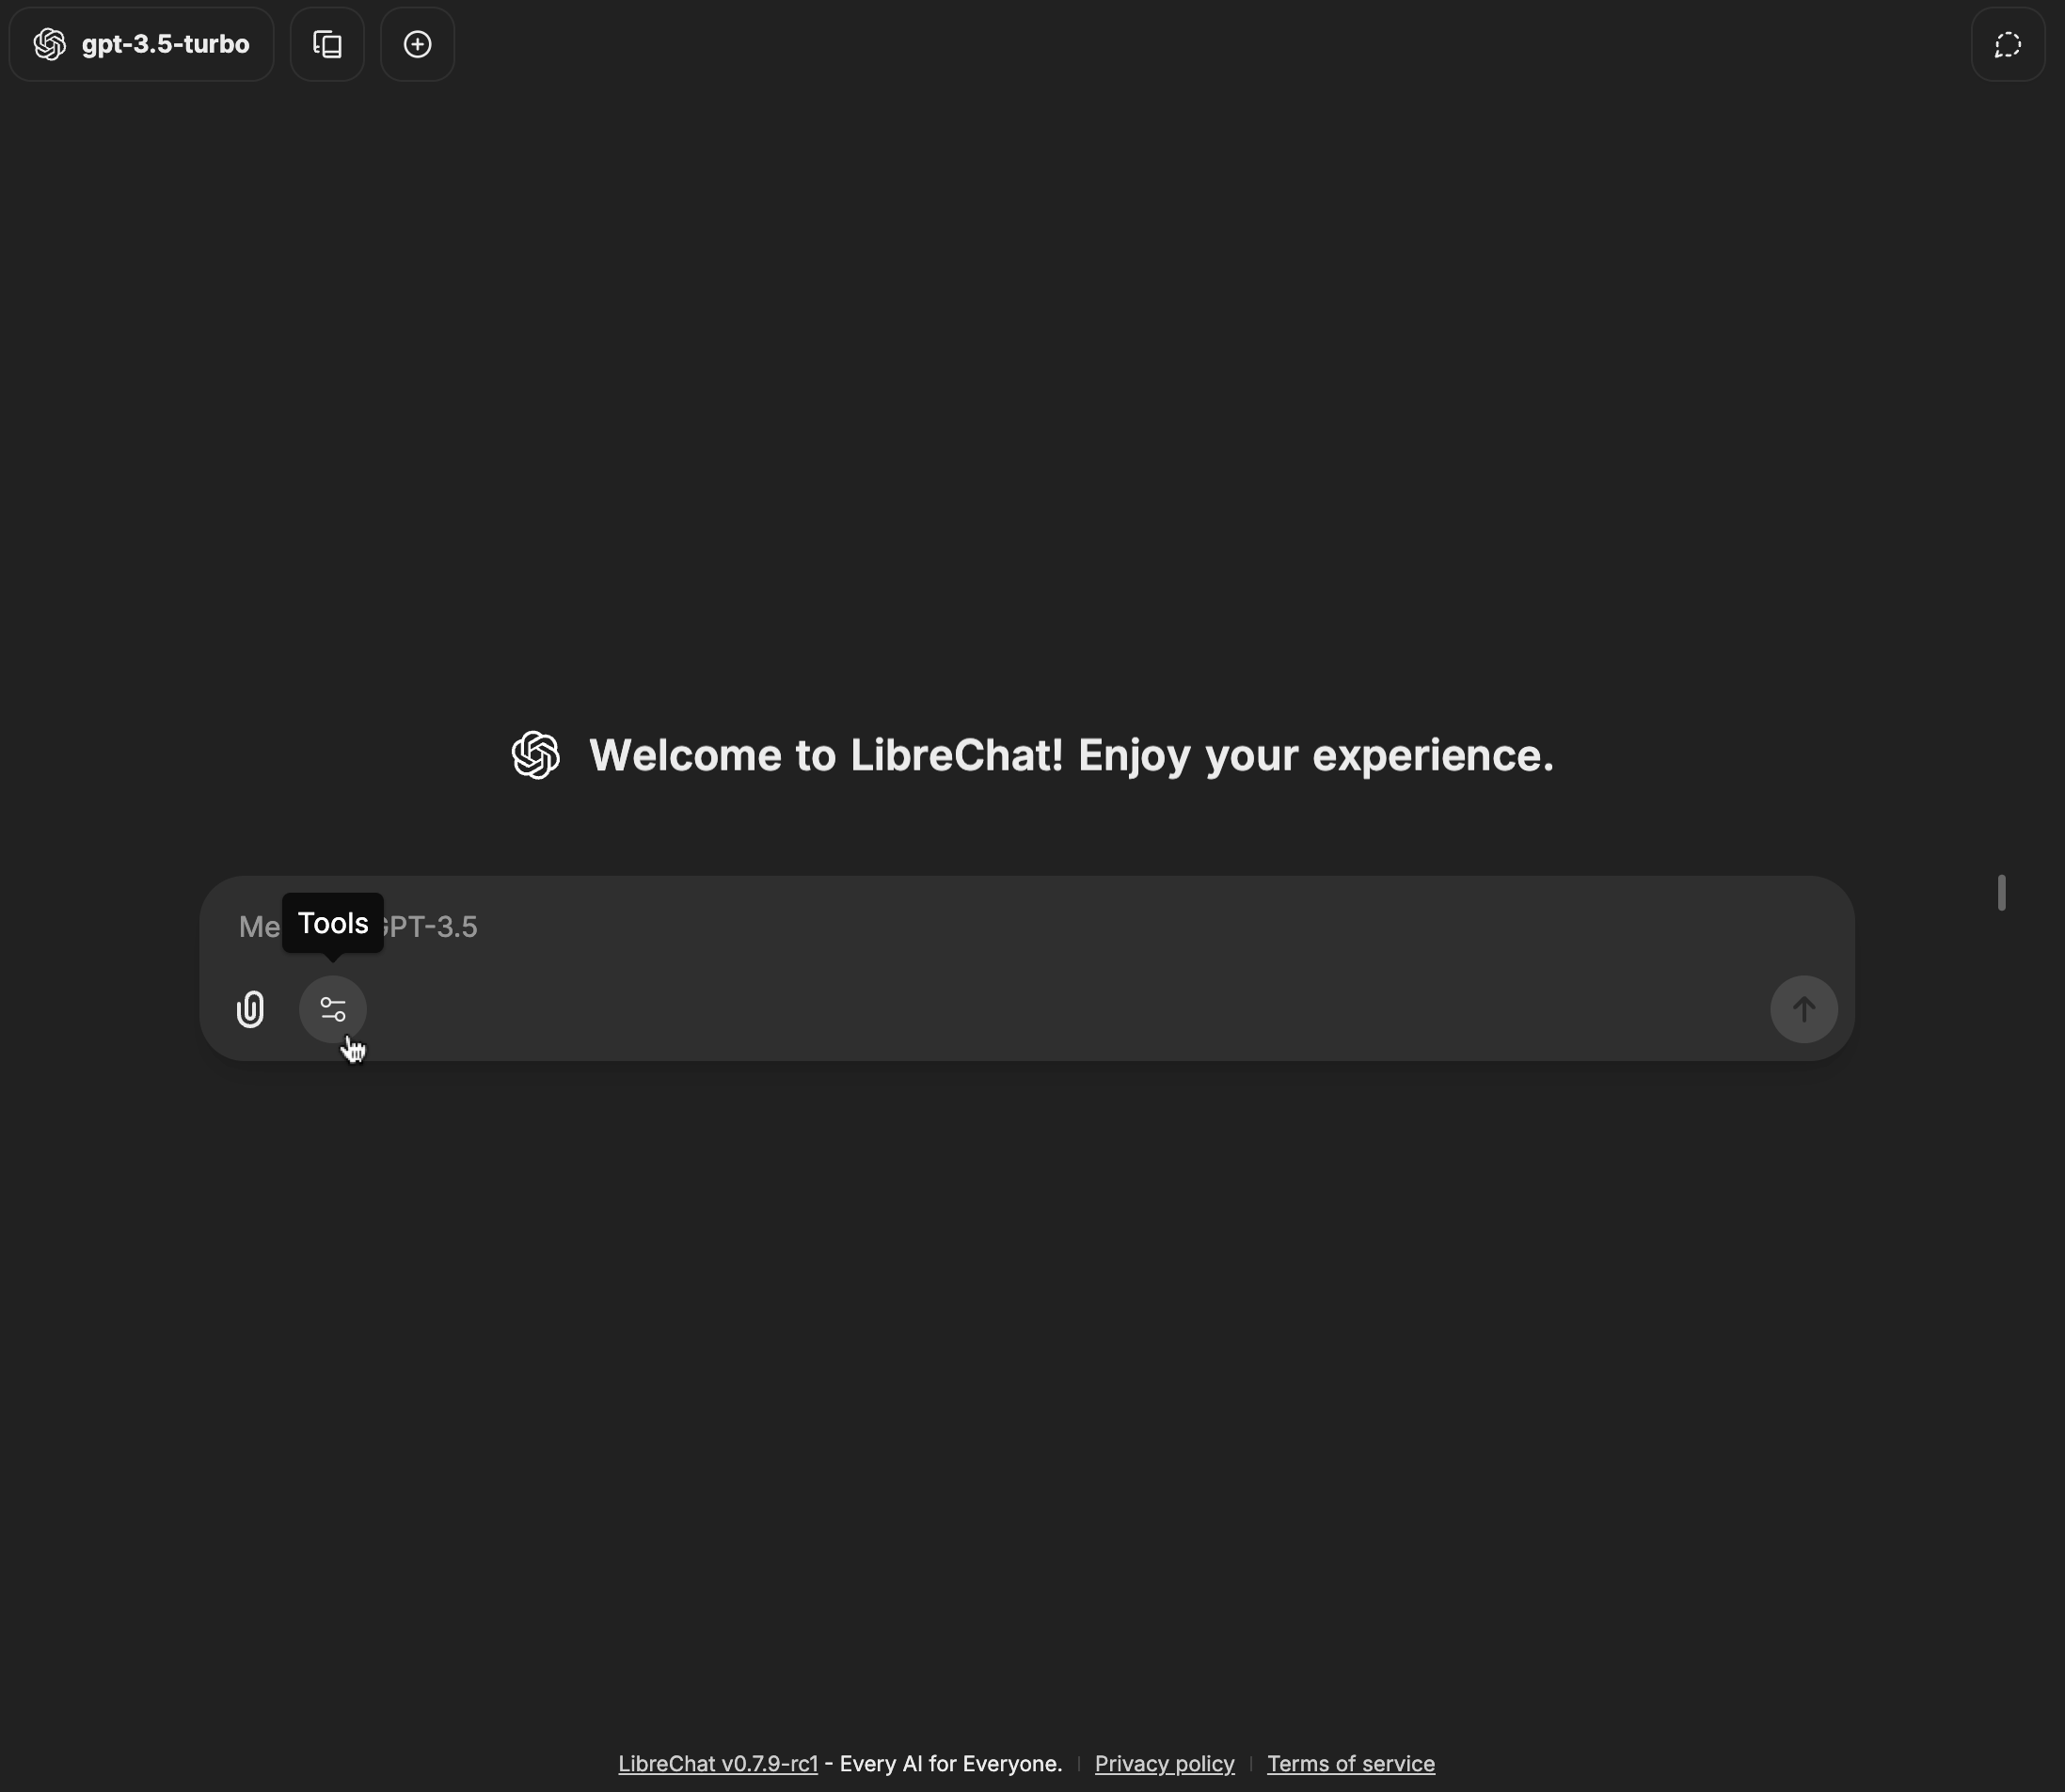
1. **Open the tools dropdown in the chat input bar**
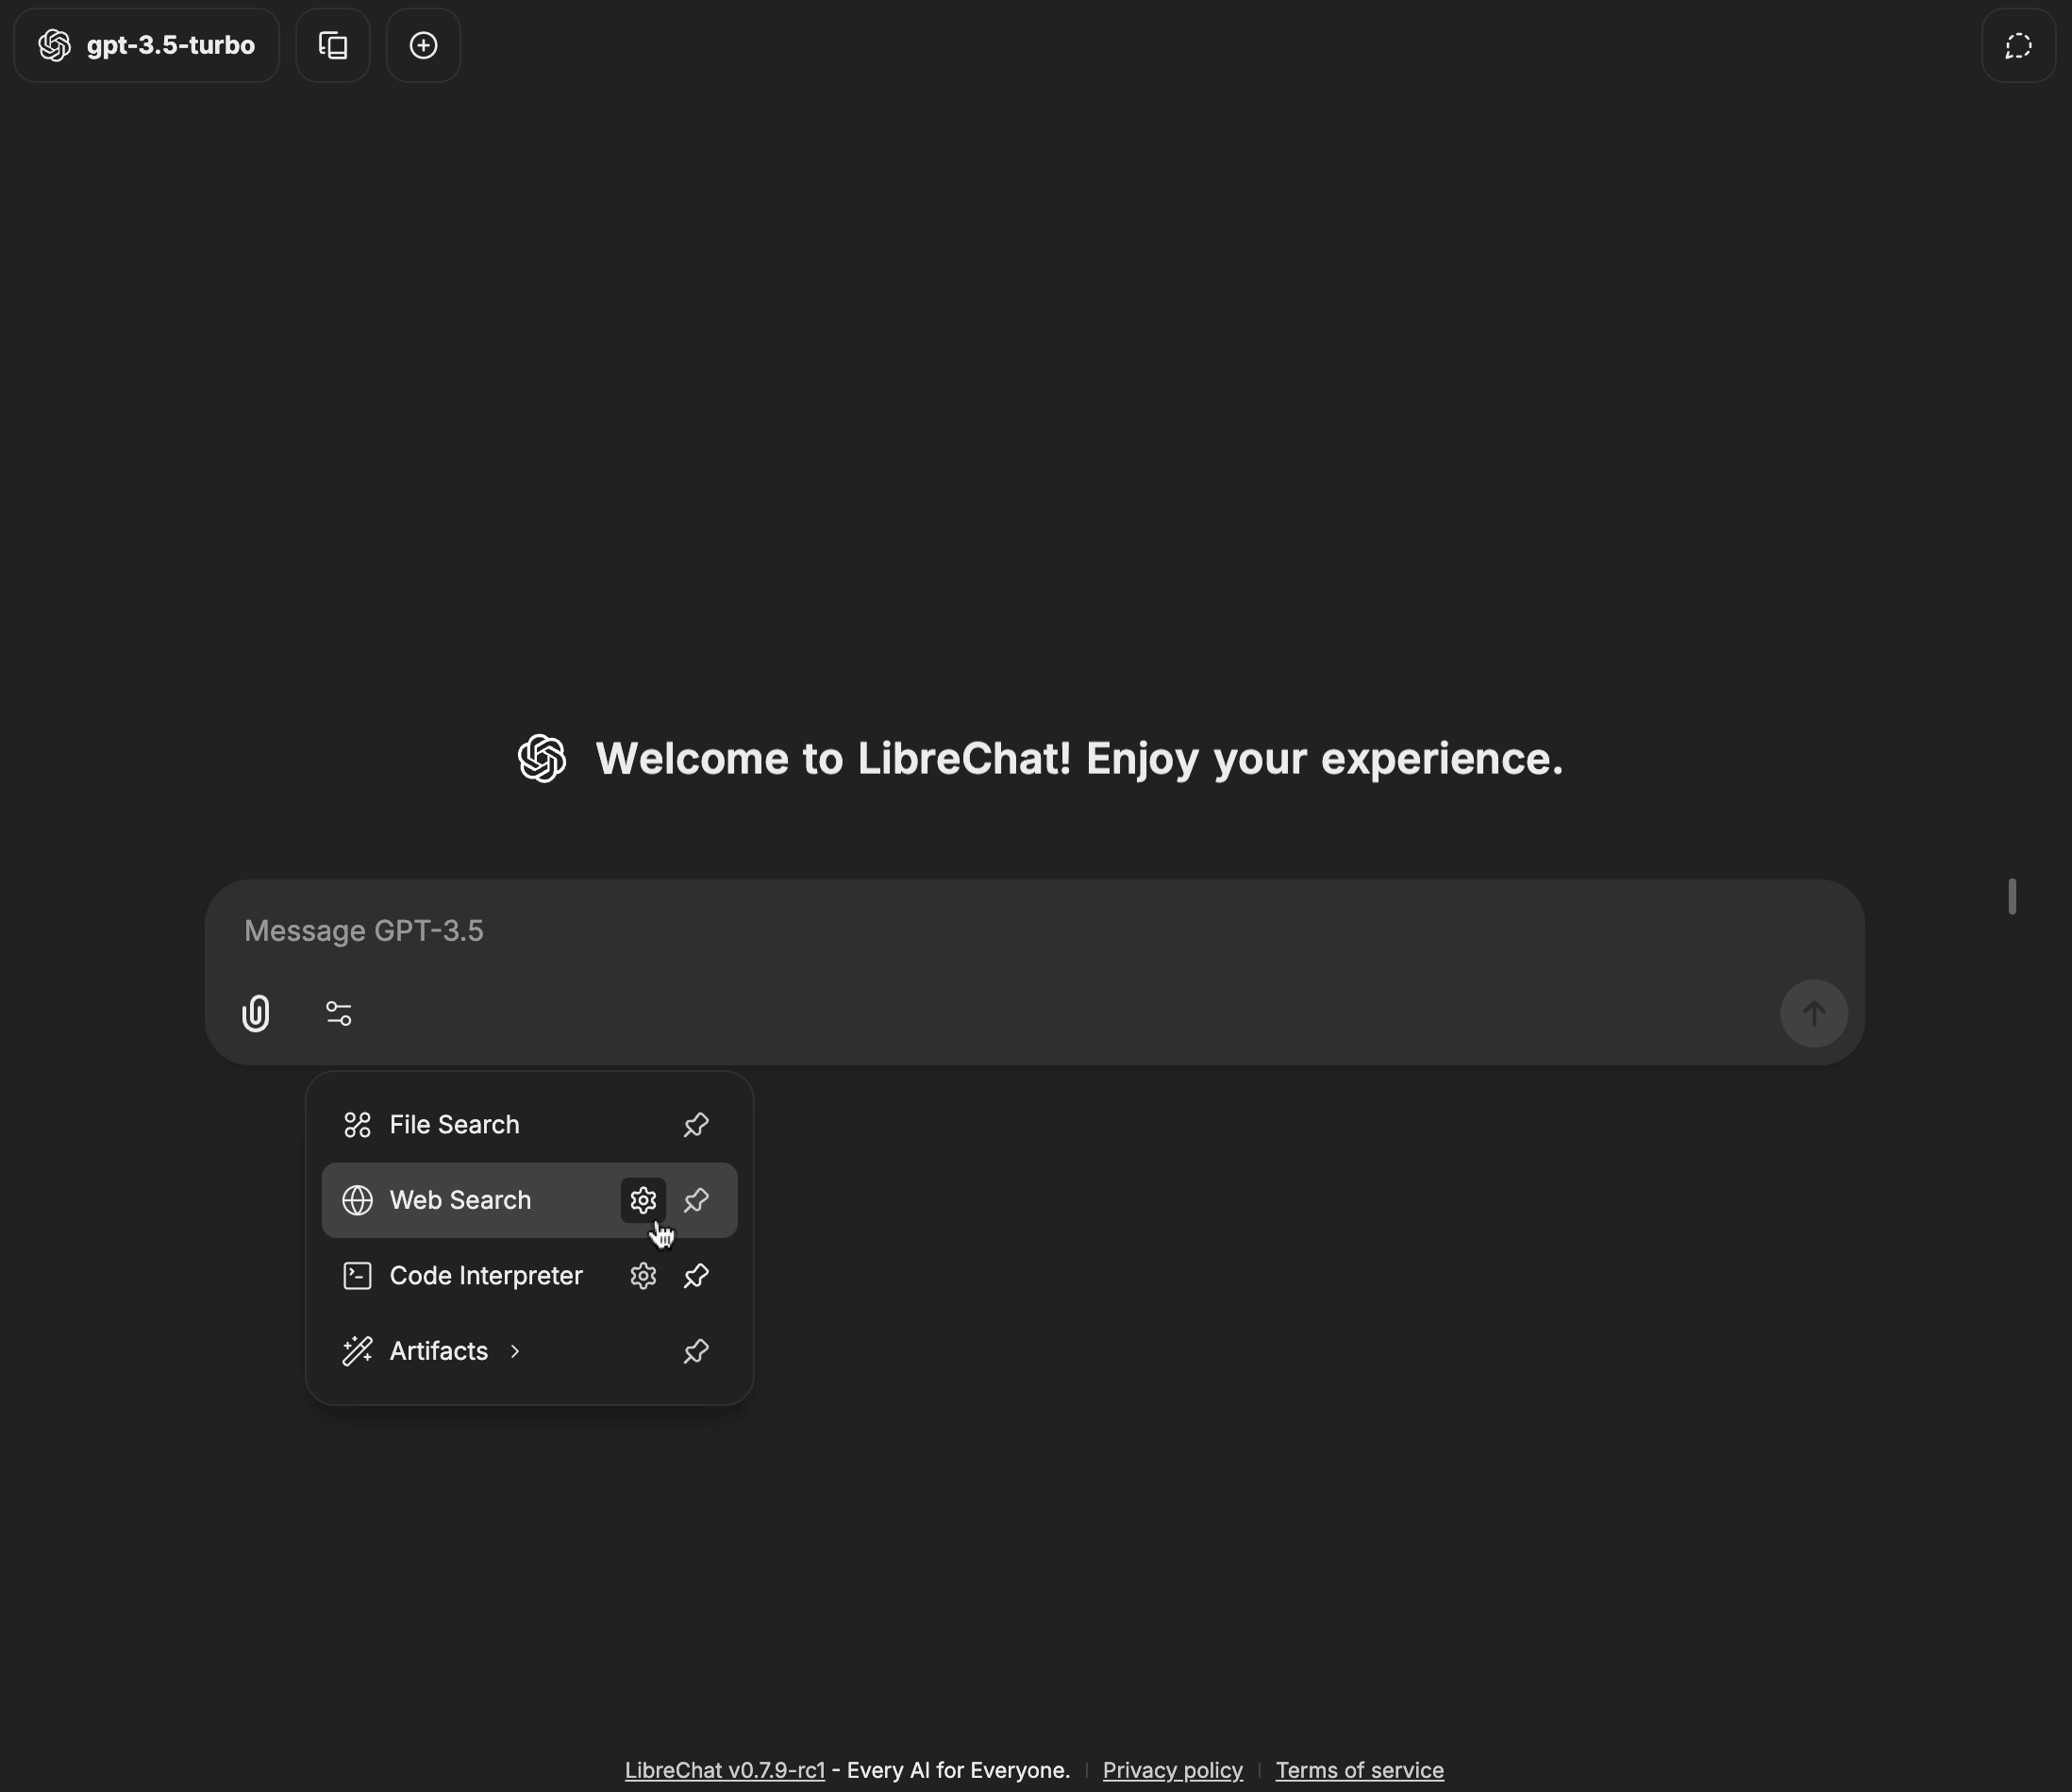
2. **Click on the gear icon next to Web Search**
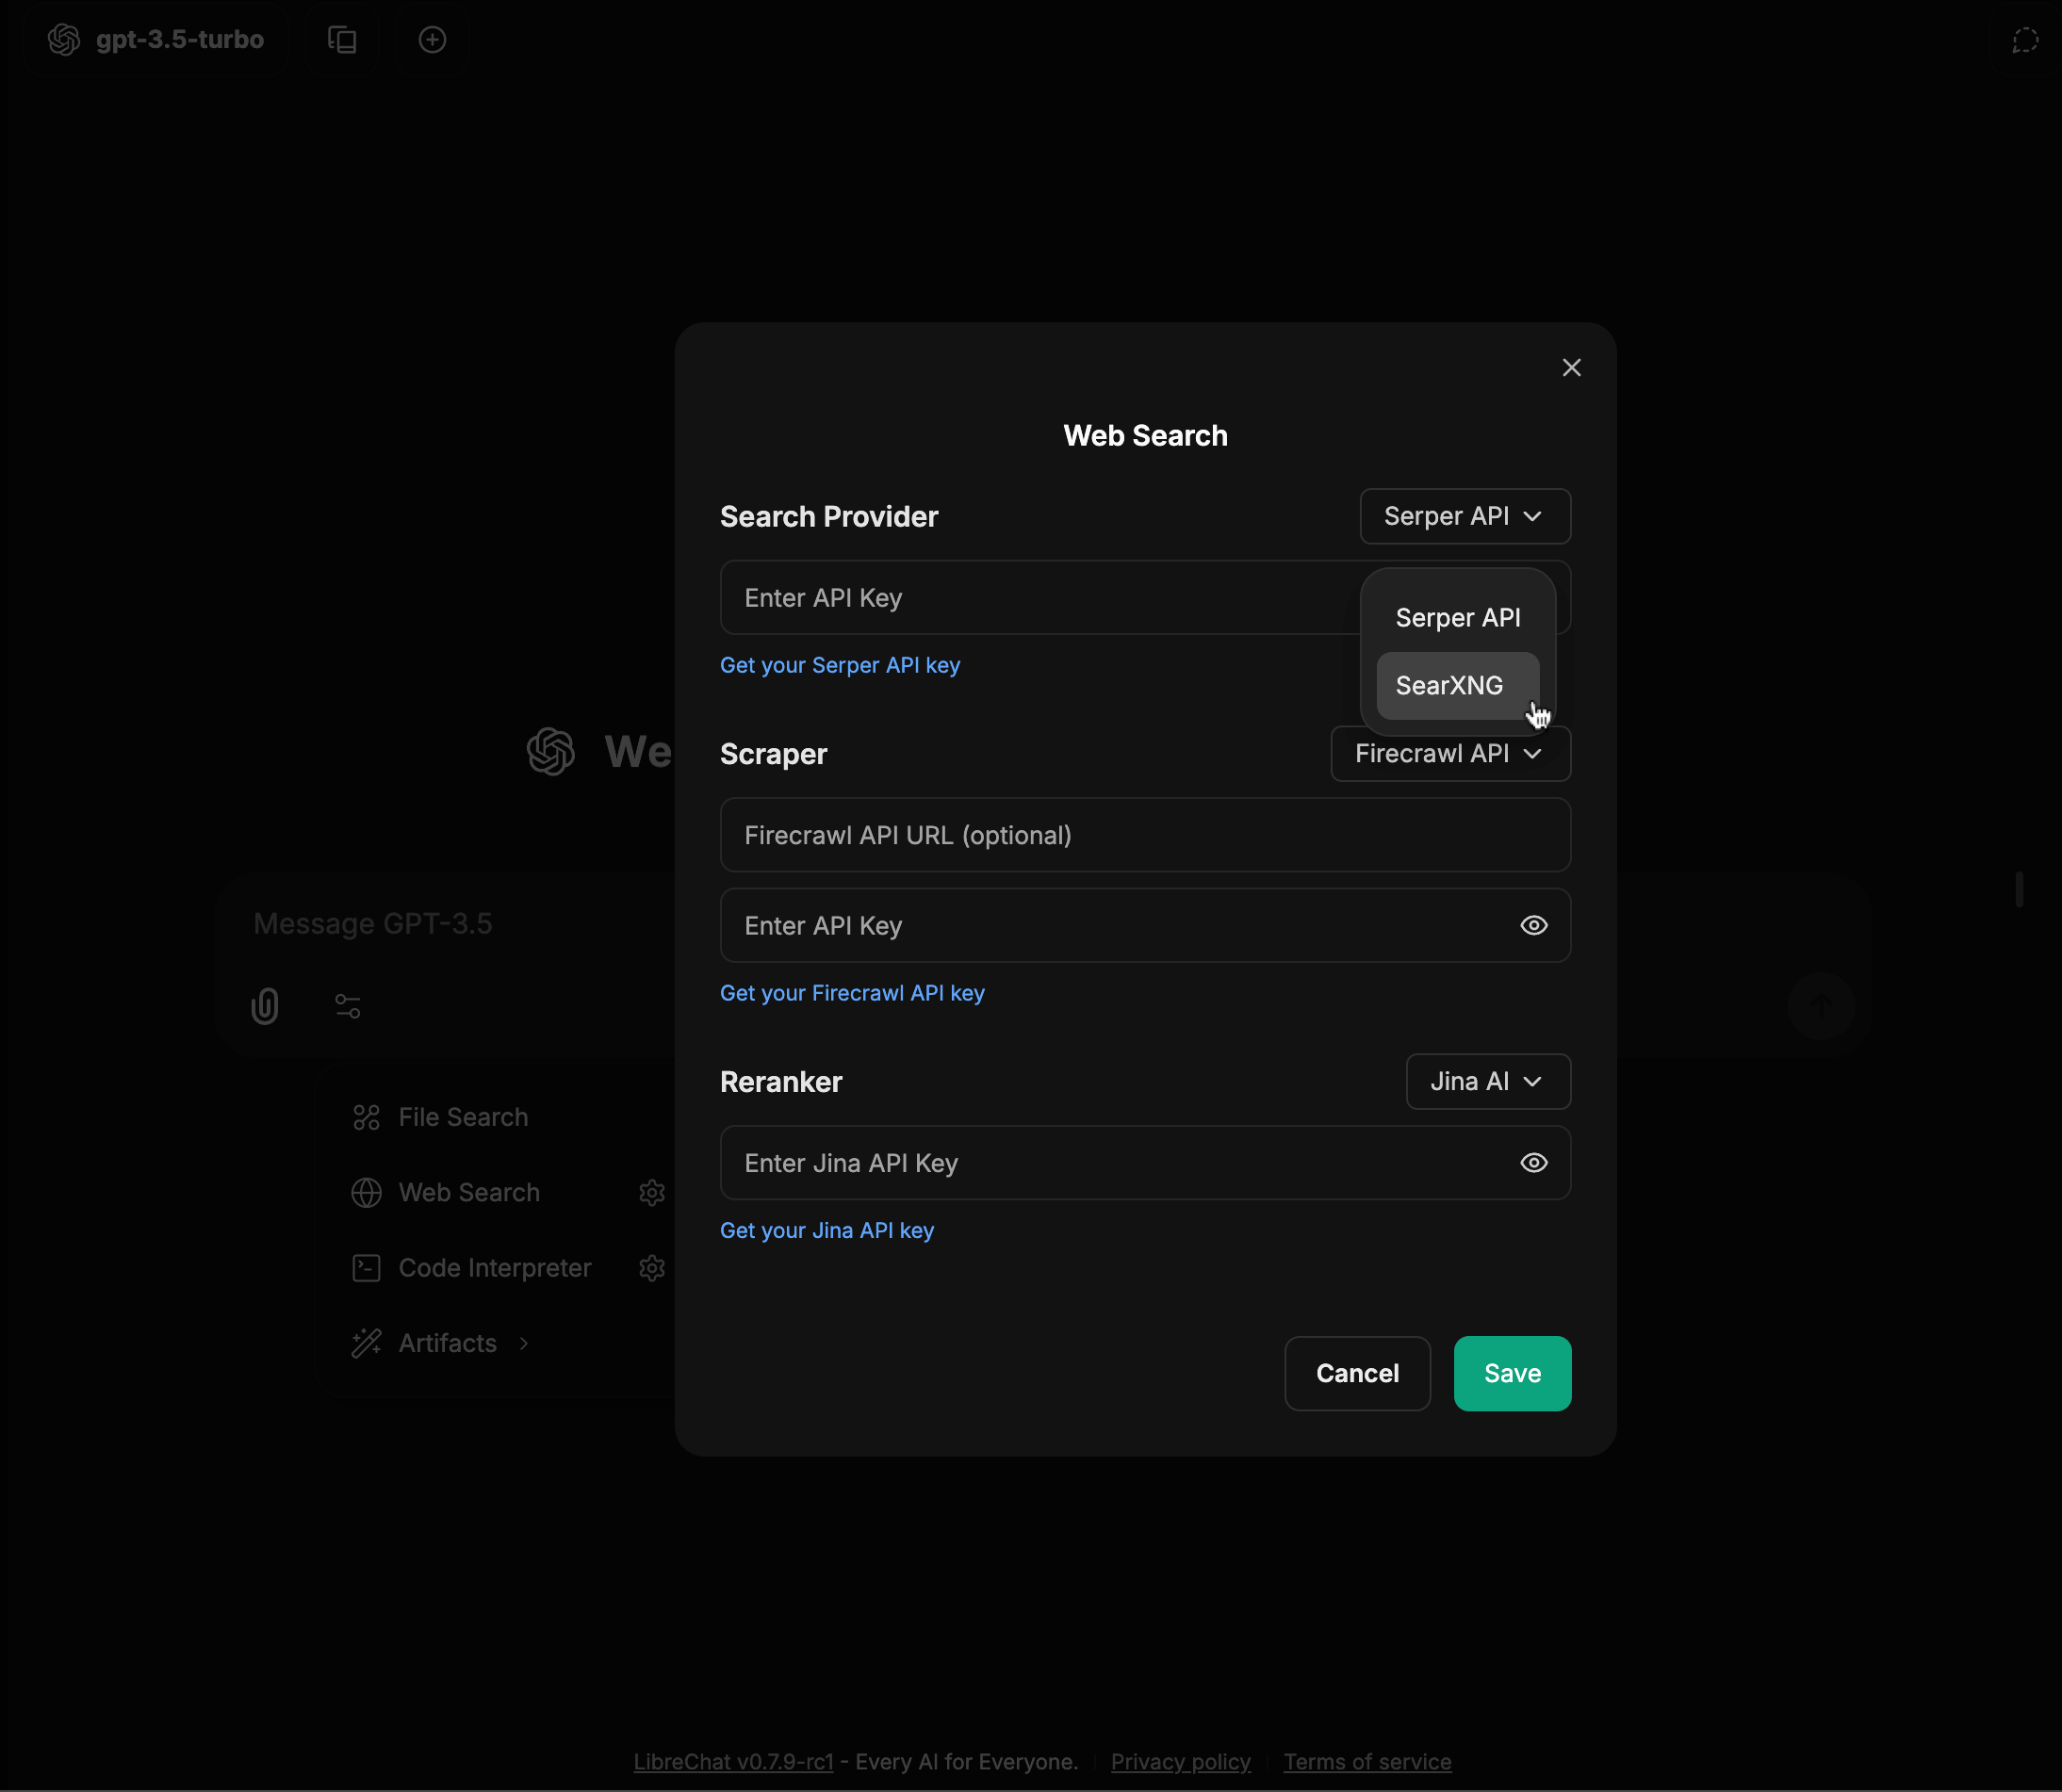
3. **Select SearXNG from the Search Provider dropdown**
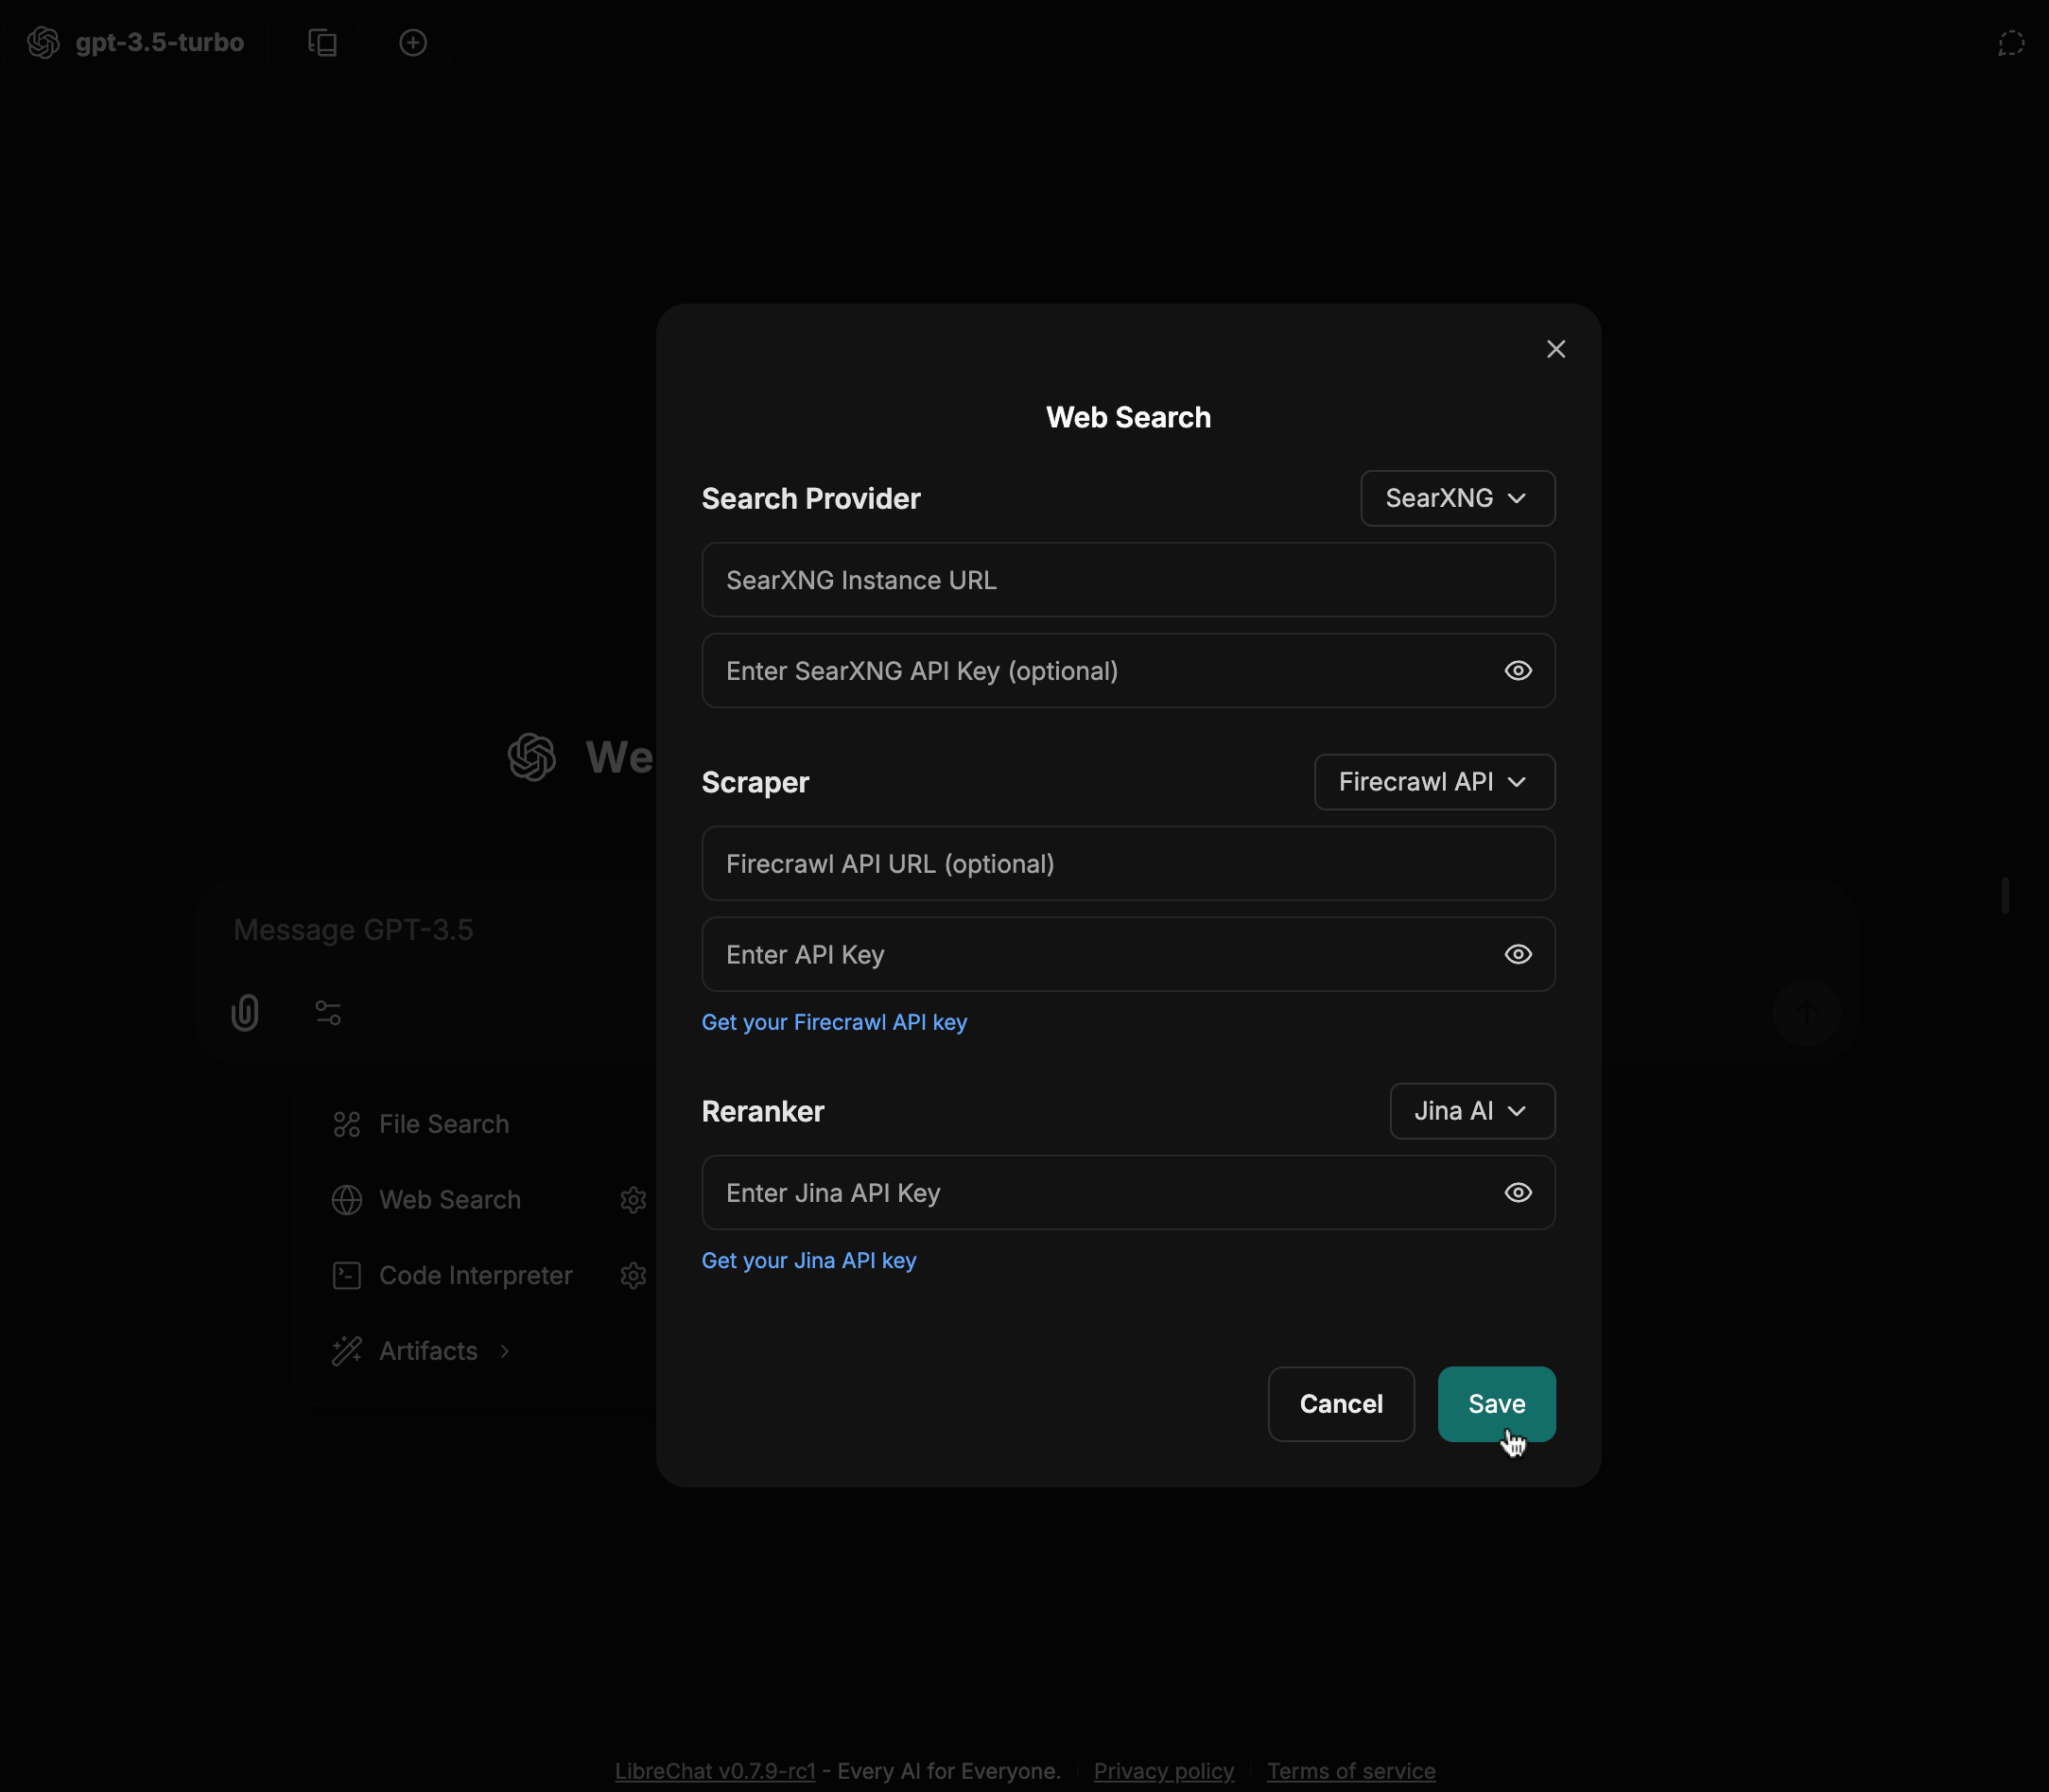
4. **Enter your configuration details (e.g. instance URL, scraper type, etc.) and click save**
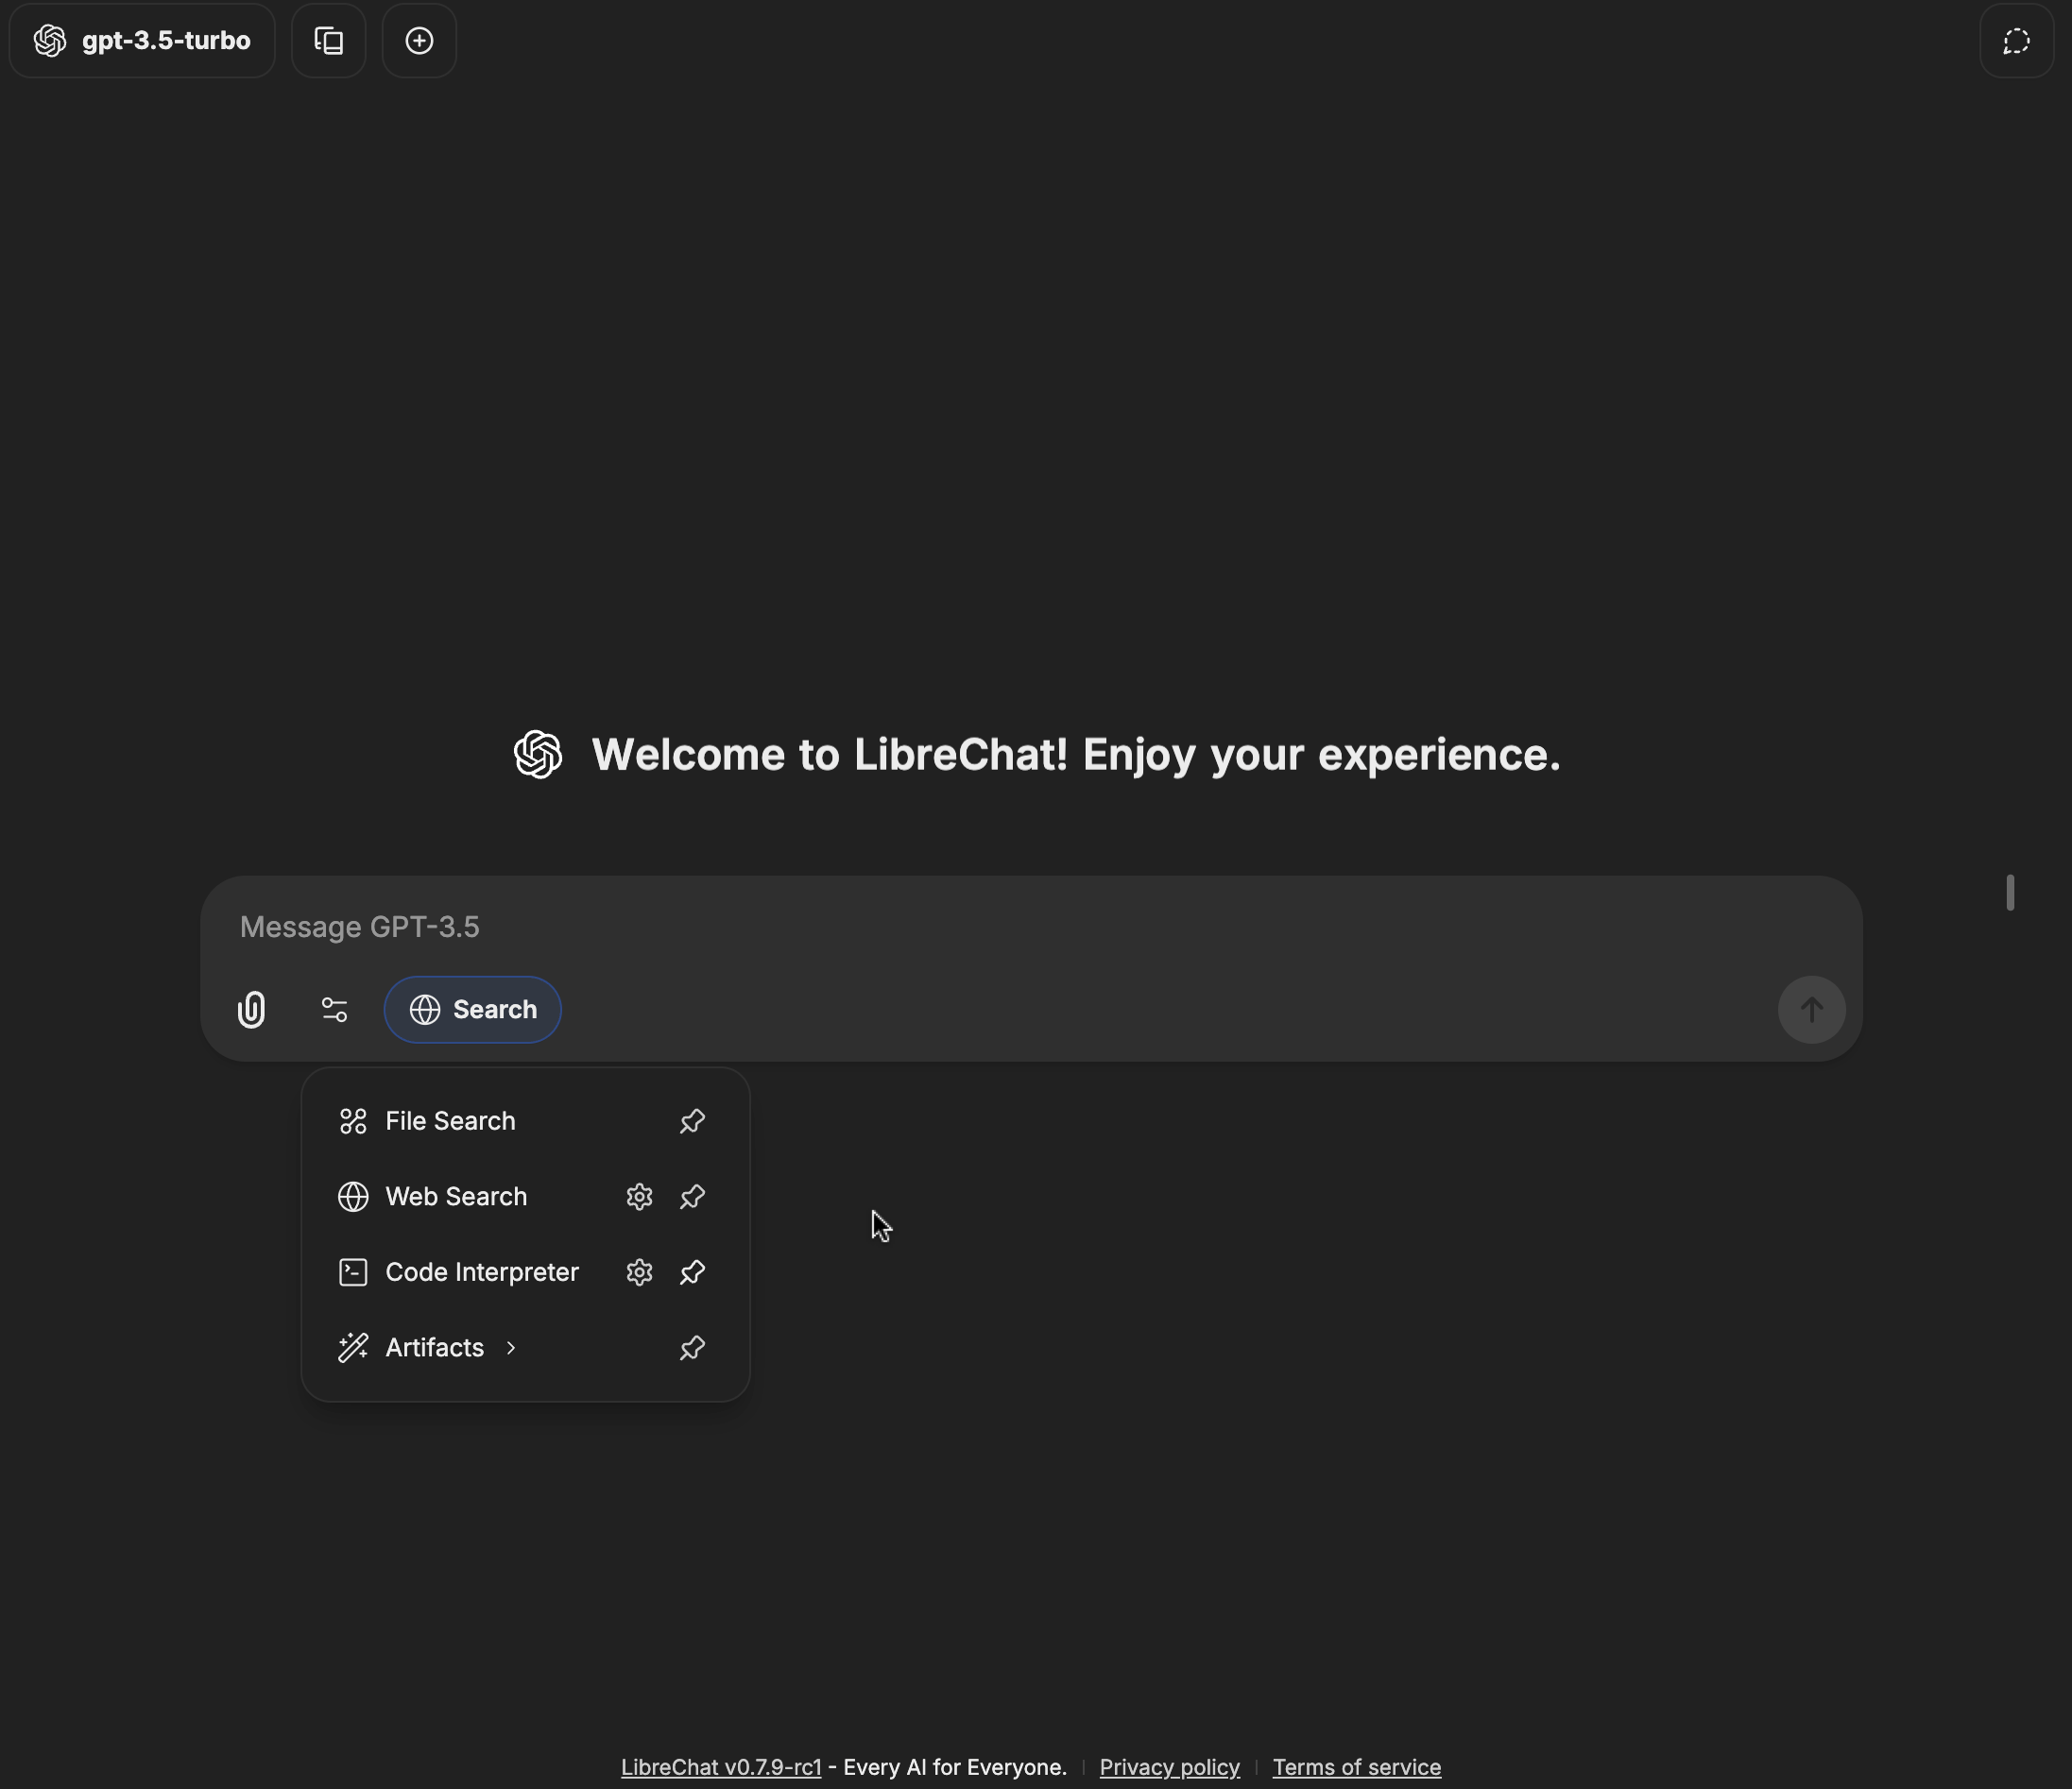
5. **Click on the Web Search option in the tools dropdown**
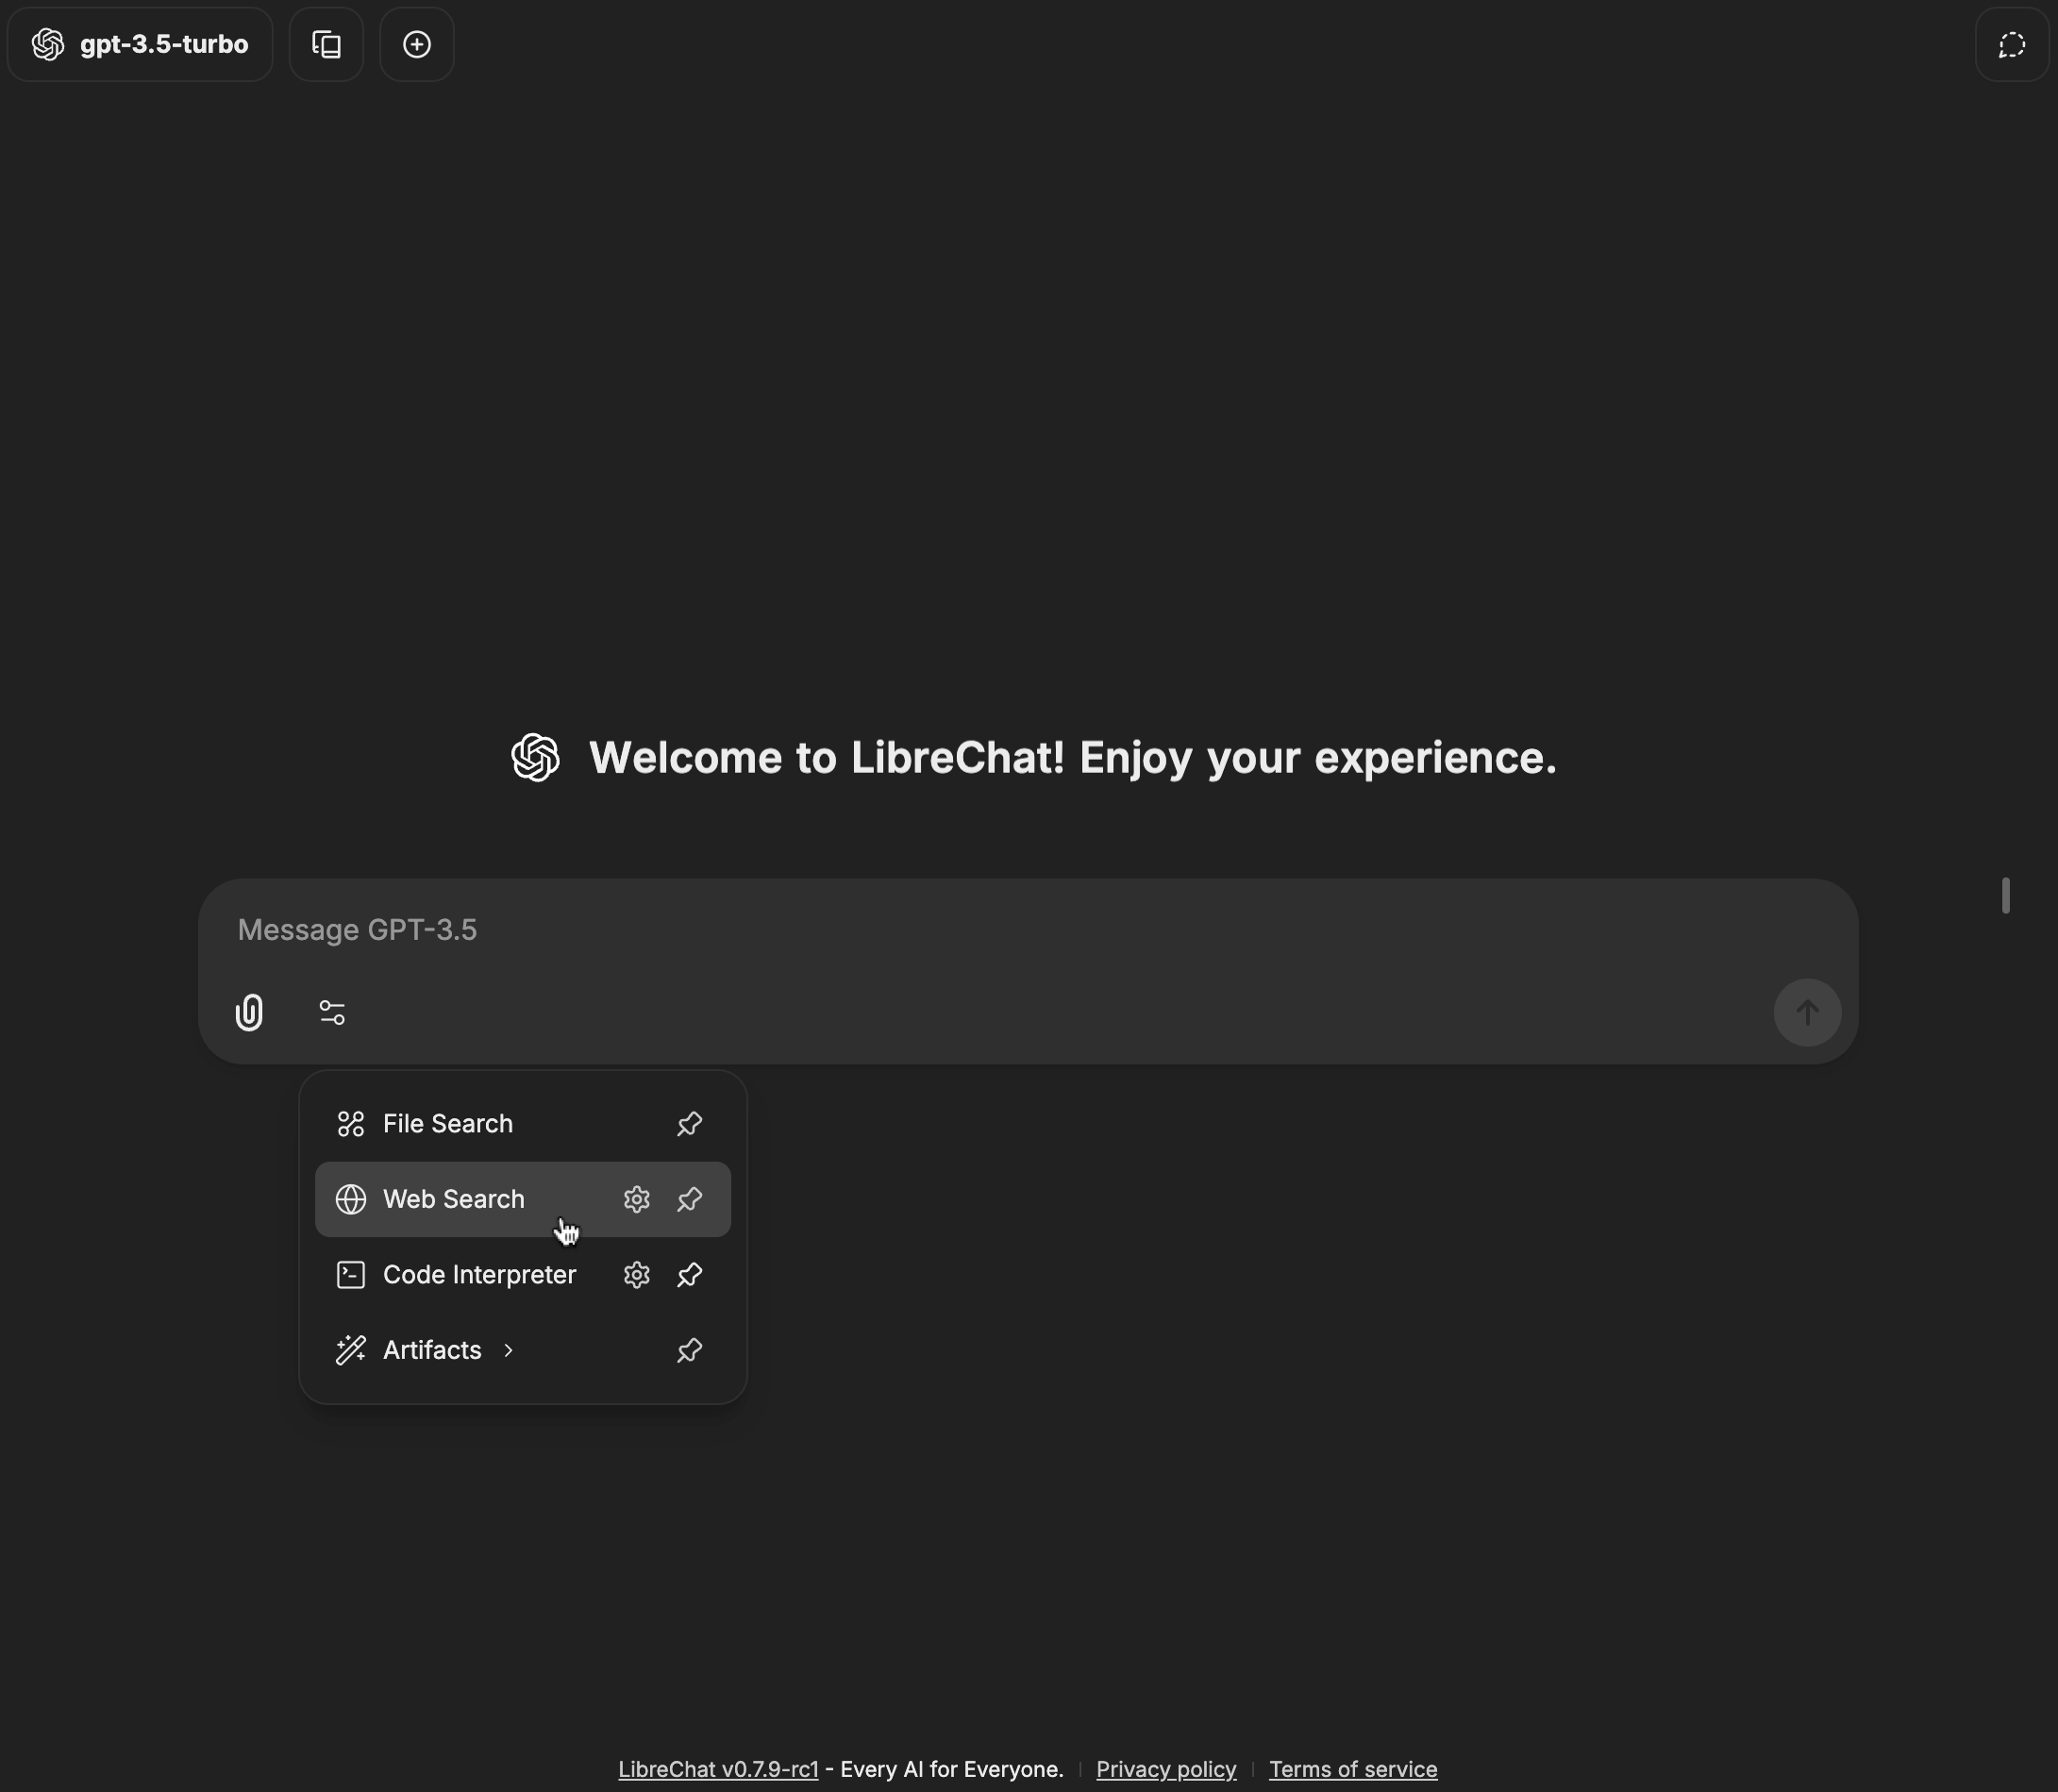
6. **The Web Search badge should now be enabled, meaning your queries can now utilize the web search functionality**
#### YAML Configuration
To configure SearXNG for everyone on the instance instead of per user, set the same values in `librechat.yaml`:
```yaml filename="librechat.yaml"
webSearch:
searchProvider: "searxng"
searxngInstanceUrl: "${SEARXNG_INSTANCE_URL}"
# searxngApiKey: "${SEARXNG_API_KEY}" # Only if your instance requires authentication
# Required: a self-hosted instance is a private destination, so exempt it from the connection guard
allowedAddresses:
- "localhost:55011"
searxngSearchOptions:
engines:
- google
- bing
- startpage
- qwant
language: "en"
timeout: 10000
```
The URL and the key are still read from the environment, so pair the config above with:
```bash filename=".env"
SEARXNG_INSTANCE_URL=http://localhost:55011
# SEARXNG_API_KEY=your_api_key
```
`localhost:55011` is a loopback address, which LibreChat's [SSRF protection](#ssrf-protection-and-private-providers) blocks at connect time. Without the matching `allowedAddresses` entry the search fails even when SearXNG is healthy. The entry must be the exact `host:port` pair from your instance URL.
When LibreChat itself runs in Docker, `localhost` is the LibreChat container, not the SearXNG one. Use a hostname the container can reach, such as the compose service name, and exempt that instead:
```yaml filename="librechat.yaml"
webSearch:
searxngInstanceUrl: "${SEARXNG_INSTANCE_URL}" # SEARXNG_INSTANCE_URL=http://searxng:8080
allowedAddresses:
- "searxng:8080"
```
See [`searxngSearchOptions`](#searxngsearchoptions) for every subkey this block accepts.
#### Troubleshooting empty results
A SearXNG search that returns nothing is almost always the request never reaching a working instance rather than LibreChat dropping results. Work through these in order:
1. **The instance is a private address with no `allowedAddresses` entry.** LibreChat blocks loopback and private destinations at connect time, so a self-hosted instance needs its exact `host:port` listed under [`allowedAddresses`](#ssrf-protection-and-private-providers). This blocks the request outright rather than returning an empty result set.
2. **`json` is missing from `formats`.** LibreChat requests results as JSON. If the `formats` section of your instance settings file does not list `json`, the instance answers with an error page and every search comes back empty. This is step 3 of the Docker setup above.
3. **Every selected engine failed.** SearXNG merges the engines that did answer, so an empty response means none of them returned anything. DuckDuckGo is in the default set (`google,bing,duckduckgo`) and serves CAPTCHAs to most self-hosted instances, which leaves only two engines to carry the search. Set `searxngSearchOptions.engines` explicitly, leave DuckDuckGo out, and list a few more engines.
4. **An engine name does not exist on your instance.** SearXNG silently skips engines it does not recognize, so a typo just means fewer results. Compare your list against `https://your-instance/config`.
5. **The instance is slower than the timeout.** Raise `searxngSearchOptions.timeout` above the default `10000` if your instance queries many engines or sits behind a slow network path.
You can reproduce what LibreChat sends by calling the instance directly:
```bash
curl -s "http://localhost:55011/search?q=librechat&format=json&engines=google,bing,startpage" | head -c 500
```
This runs from your own machine, so it bypasses LibreChat's connection guard entirely. An empty `results` array here confirms the problem is on the SearXNG side; results here while LibreChat still finds nothing points back at `allowedAddresses`.