# RAG API (https://www.librechat.ai/docs/configuration/rag_api)
The RAG API indexes user-uploaded files and retrieves relevant passages to augment your prompts, giving LibreChat context-aware responses grounded in your documents. It runs as a separate FastAPI service backed by a PostgreSQL + pgvector database.
The [RAG API Presentation](/docs/features/rag_api) explains the concept in more detail and links to a helpful video. This page covers setup and configuration.
## Availability
RAG works with [Agents](/docs/features/agents), as well as Custom Endpoints, OpenAI, Azure OpenAI, Anthropic, and Google.
OpenAI Assistants have their own RAG implementation through the "Retrieval" capability ([details here](https://platform.openai.com/docs/assistants/tools/knowledge-retrieval)). Using the RAG API with the Assistants API is still worthwhile since OpenAI charges for both file storage and Retrieval. This integration is planned for a future update.
## Docker Quick Start
For Docker, the RAG API is already wired up in both the default `docker-compose.yml` and `deploy-compose.yml` files, including the `RAG_API_URL` value. You only need to make sure you are running the latest image and compose files. See the [Updating LibreChat guide for Docker](/docs/local/docker#update-librechat) if you are unsure how to update.
With the default Docker setup, the `.env` file is shared between LibreChat and the RAG API. Define the RAG variables in that same file. The full list lives in the [RAG API README](https://github.com/danny-avila/rag_api/blob/main/README.md).
Pick the embeddings provider you want to use.
**Use RAG with OpenAI embeddings.** This is the default configuration.
**Set the RAG API URL.** Add the following to your `.env` file:
```bash filename=".env"
RAG_API_URL=http://host.docker.internal:8000
```
**Provide an OpenAI API key (if needed).** If your OpenAI API key is set to `user_provided`, add a key for embeddings. Skip this step if you already supply the OpenAI key in your `.env` file.
```bash filename=".env"
RAG_OPENAI_API_KEY=sk-your-openai-api-key-example
```
**Start the containers.**
```bash
docker compose up -d
```
**Use RAG with Hugging Face embeddings.**
**Configure the provider.** Add the following to your `.env` file:
```bash filename=".env"
RAG_API_URL=http://host.docker.internal:8000
EMBEDDINGS_PROVIDER=huggingface
HF_TOKEN=hf_xxxxxxxxxxxxxxxxxxxxxxx
```
**Switch to the full RAG API image.** Update your `docker-compose.override.yml` file:
```yaml filename="docker-compose.override.yml"
version: '3.4'
services:
rag_api:
image: registry.librechat.ai/danny-avila/librechat-rag-api-dev:latest
```
**Start the containers.**
```bash
docker compose up -d
```
**Use RAG with Ollama local embeddings.**
You need Ollama and the `nomic-embed-text` embedding model. Pull it with `ollama pull nomic-embed-text`.
**Configure the provider.** Add the following to your `.env` file:
```bash filename=".env"
RAG_API_URL=http://host.docker.internal:8000
EMBEDDINGS_PROVIDER=ollama
OLLAMA_BASE_URL=http://host.docker.internal:11434
EMBEDDINGS_MODEL=nomic-embed-text
```
**Switch to the full RAG API image.** Update your `docker-compose.override.yml` file:
```yaml filename="docker-compose.override.yml"
version: '3.4'
services:
rag_api:
image: registry.librechat.ai/danny-avila/librechat-rag-api-dev:latest
# If running on Linux
# extra_hosts:
# - "host.docker.internal:host-gateway"
```
**Start the containers.**
```bash
docker compose up -d
```
### Lite vs. full image
Docker uses the "lite" image of the RAG API by default (`registry.librechat.ai/danny-avila/librechat-rag-api-dev-lite:latest`), which only supports remote embeddings from OpenAI or a remote HuggingFace/Ollama service you have configured.
For local embeddings, switch the image in the compose file to the full build, `registry.librechat.ai/danny-avila/librechat-rag-api-dev:latest`. Make this change in your [Docker Compose Override File](/docs/configuration/docker_override). See `docker-compose.override.yml.example` at the root of the project for an example.
If you want a compose file that includes only the PostgreSQL + pgvector database and the Python API, see `rag.yml` at the root of the project.
### Database storage
The default compose files store the pgvector/PostgreSQL data in the Docker-managed `pgdata2` volume. This is intentional: the database files don't need to be edited directly from the host, and a managed volume avoids common ownership and permission problems. User-facing, editable files (uploads, logs, images, MongoDB data, and NGINX config) are bind-mounted to project folders where direct host access is useful.
## Local Setup
A non-container setup is more hands-on. Follow the instructions in the [RAG API repo](https://github.com/danny-avila/rag_api/).
Set `RAG_API_URL` in your LibreChat `.env` file to wherever the API is reachable from your setup. This differs from Docker, where the value is already set in the default `docker-compose.yml` file.
## Configuration
Set RAG API options through environment variables in an `.env` file accessible to the API. Most are optional, aside from the credentials and paths required by your chosen provider. In the default setup, only `RAG_OPENAI_API_KEY` is required.
### Environment Variables
`OPENAI_API_KEY` works for RAG embeddings, but `RAG_OPENAI_API_KEY` overrides it to avoid credential conflicts.
For the complete list of variables and their descriptions, see the [RAG API repo](https://github.com/danny-avila/rag_api/).
## Usage
Once the RAG API is running, it integrates with LibreChat automatically. When a user uploads files to a conversation, the API indexes them and uses them for context-aware responses.
**Upload files to the conversation.** If `RAG_API_URL` is not configured or not reachable, the upload fails.
**Chat as usual.** As the user interacts with the model, the RAG API retrieves relevant passages from the indexed files based on the input and uses them to augment the prompt.
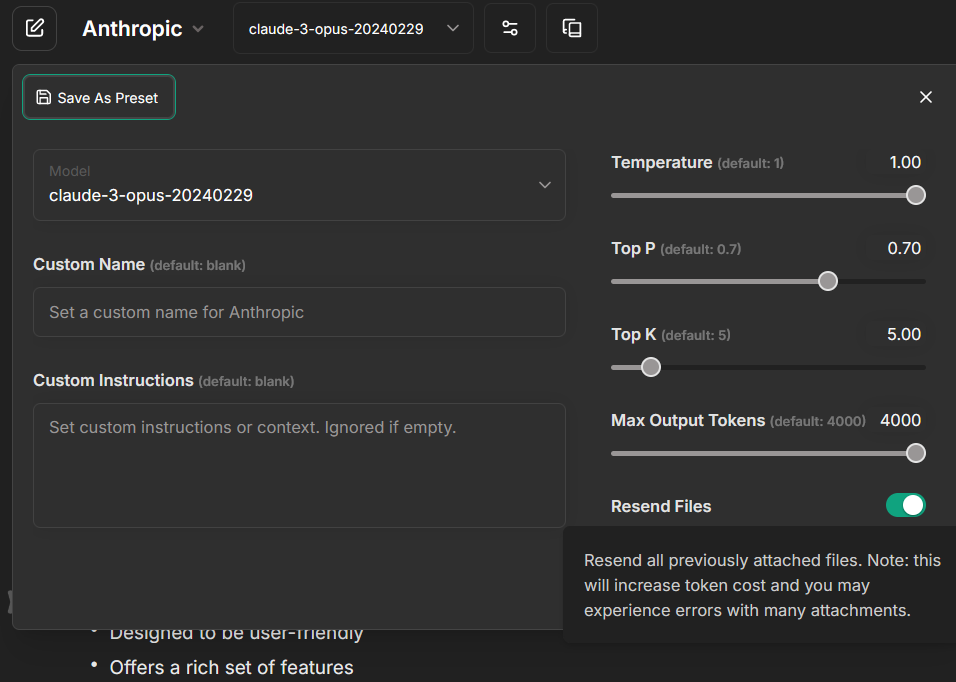
**Control when files are queried.** By default, the vector store is queried on every new message in a conversation that has a file attached. Craft your prompts accordingly.
Toggle **Resend Files** off in the conversation settings to query files only when they are explicitly attached to a message.
**Reuse indexed files.** Upload a file once, then attach it to any new message or conversation from the Side Panel.
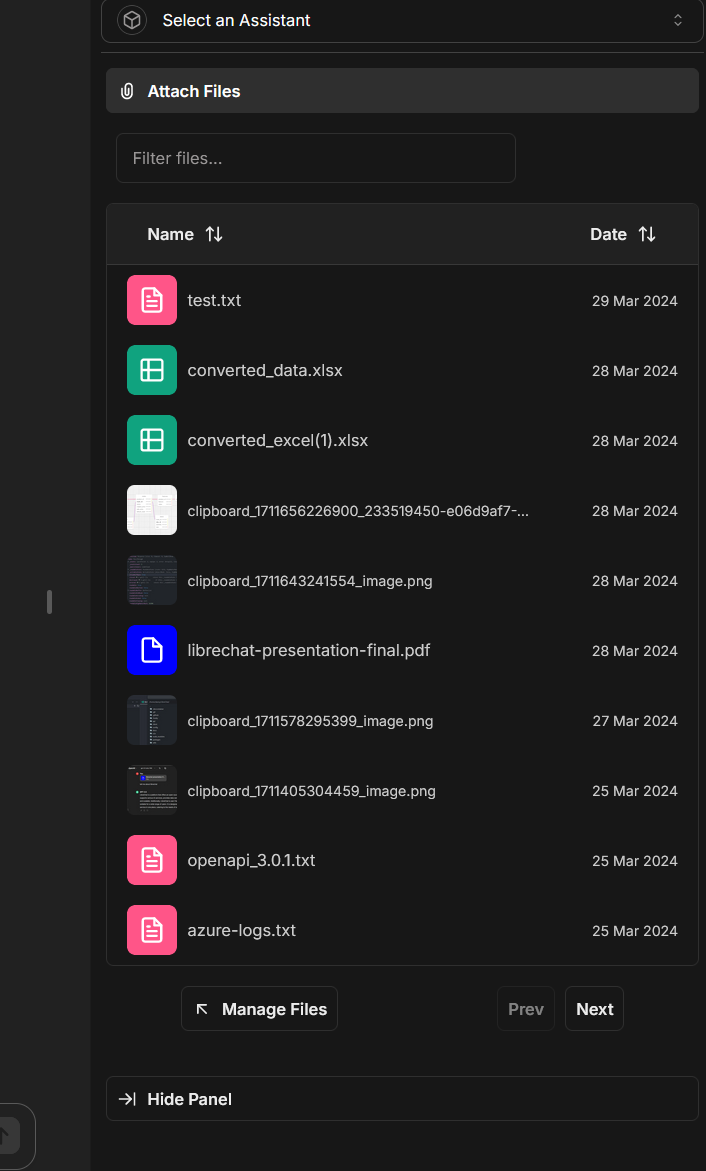
Files must be in "Host" storage. "OpenAI" files are treated differently and are exclusive to Assistants, so they must not have been uploaded while the Assistants endpoint was selected and active. View and manage your files from the Side Panel.
## Troubleshooting
If you run into issues setting up or using the RAG API:
- Confirm all required environment variables are set correctly in your `.env` file.
- Make sure the vector database is configured and accessible.
- Verify that the OpenAI API key or other provider credentials are valid.
- Check both the LibreChat and RAG API logs for errors or warnings.
If the problem persists, refer to the RAG API documentation or ask the LibreChat community on GitHub Discussions or Discord.